


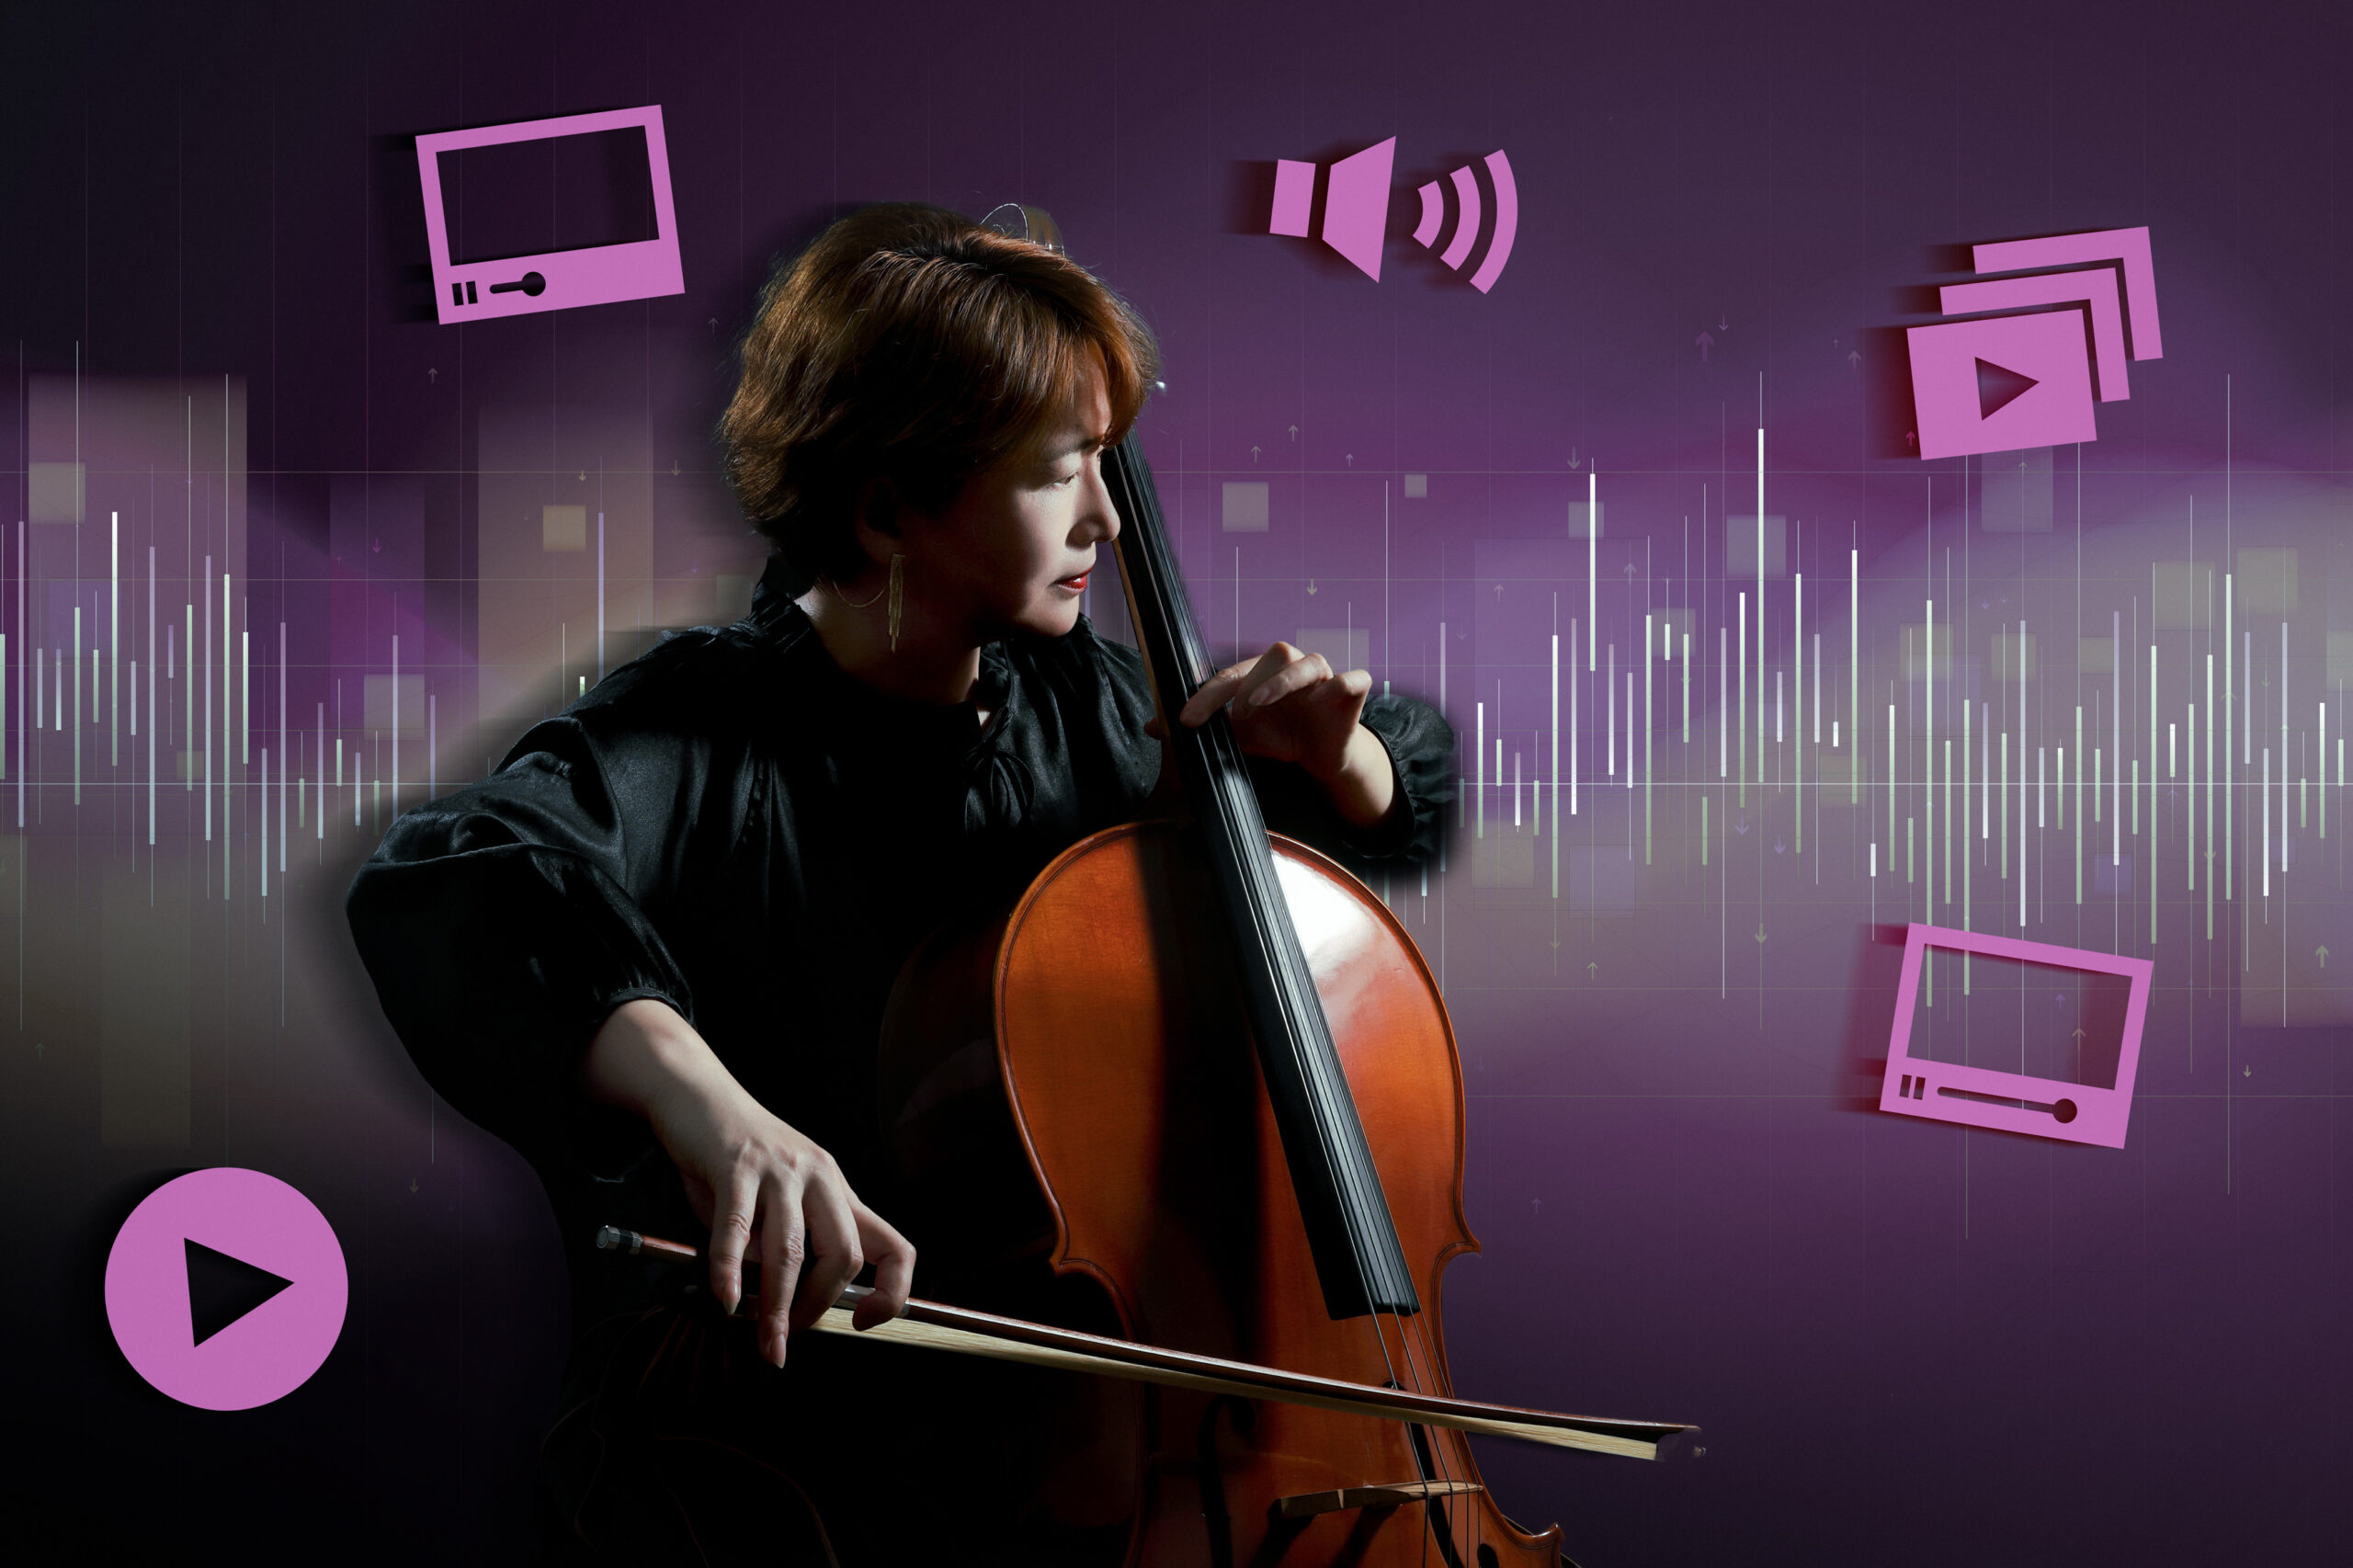
Humans naturally learn by making connections between sight and sound. For instance, we can watch someone playing the cello and recognize that the cellist’s movements are generating the music we hear.A new approach developed by researchers from MIT and elsewhere improves an AI model’s ability to learn in this same fashion. This could be useful in applications such as journalism and film production, where the model could help with curating multimodal content through automatic video and audio retrieval.In the longer term, this work could be used to improve a robot’s ability to understand real-world environments, where auditory and visual information are often closely connected.Improving upon prior work from their group, the researchers created a method that helps machine-learning models align corresponding audio and visual data from video clips without the need for human labels.They adjusted how their original model is trained so it learns a finer-grained correspondence between a particular video frame and the audio that occurs in that moment. The researchers also made some architectural tweaks that help the system balance two distinct learning objectives, which improves performance.Taken together, these relatively simple improvements boost the accuracy of their approach in video retrieval tasks and in classifying the action in audiovisual scenes. For instance, the new method could automatically and precisely match the sound of a door slamming with the visual of it closing in a video clip.“We are building AI systems that can process the world like humans do, in terms of having both audio and visual information coming in at once and being able to seamlessly process both modalities. Looking forward, if we can integrate this audio-visual technology into some of the tools we use on a daily basis, like large language models, it could open up a lot of new applications,” says Andrew Rouditchenko, an MIT graduate student and co-author of a paper on this research.He is joined on the paper by lead author Edson Araujo, a graduate student at Goethe University in Germany; Yuan Gong, a former MIT postdoc; Saurabhchand Bhati, a current MIT postdoc; Samuel Thomas, Brian Kingsbury, and Leonid Karlinsky of IBM Research; Rogerio Feris, principal scientist and manager at the MIT-IBM Watson AI Lab; James Glass, senior research scientist and head of the Spoken Language Systems Group in the MIT Computer Science and Artificial Intelligence Laboratory (CSAIL); and senior author Hilde Kuehne, professor of computer science at Goethe University and an affiliated professor at the MIT-IBM Watson AI Lab. The work will be presented at the Conference on Computer Vision and Pattern Recognition.Syncing upThis work builds upon a machine-learning method the researchers developed a few years ago, which provided an efficient way to train a multimodal model to simultaneously process audio and visual data without the need for human labels.The researchers feed this model, called CAV-MAE, unlabeled video clips and it encodes the visual and audio data separately into representations called tokens. Using the natural audio from the recording, the model automatically learns to map corresponding pairs of audio and visual tokens close together within its internal representation space.They found that using two learning objectives balances the model’s learning process, which enables CAV-MAE to understand the corresponding audio and visual data while improving its ability to recover video clips that match user queries.But CAV-MAE treats audio and visual samples as one unit, so a 10-second video clip and the sound of a door slamming are mapped together, even if that audio event happens in just one second of the video.In their improved model, called CAV-MAE Sync, the researchers split the audio into smaller windows before the model computes its representations of the data, so it generates separate representations that correspond to each smaller window of audio.During training, the model learns to associate one video frame with the audio that occurs during just that frame.“By doing that, the model learns a finer-grained correspondence, which helps with performance later when we aggregate this information,” Araujo says.They also incorporated architectural improvements that help the model balance its two learning objectives.Adding “wiggle room”The model incorporates a contrastive objective, where it learns to associate similar audio and visual data, and a reconstruction objective which aims to recover specific audio and visual data based on user queries.In CAV-MAE Sync, the researchers introduced two new types of data representations, or tokens, to improve the model’s learning ability.They include dedicated “global tokens” that help with the contrastive learning objective and dedicated “register tokens” that help the model focus on important details for the reconstruction objective.“Essentially, we add a bit more wiggle room to the model so it can perform each of these two tasks, contrastive and reconstructive, a bit more independently. That benefitted overall performance,” Araujo adds.While the researchers had some intuition these enhancements would improve the performance of CAV-MAE Sync, it took a careful combination of strategies to shift the model in the direction they wanted it to go.“Because we have multiple modalities, we need a good model for both modalities by themselves, but we also need to get them to fuse together and collaborate,” Rouditchenko says.In the end, their enhancements improved the model’s ability to retrieve videos based on an audio query and predict the class of an audio-visual scene, like a dog barking or an instrument playing.Its results were more accurate than their prior work, and it also performed better than more complex, state-of-the-art methods that require larger amounts of training data.“Sometimes, very simple ideas or little patterns you see in the data have big value when applied on top of a model you are working on,” Araujo says.In the future, the researchers want to incorporate new models that generate better data representations into CAV-MAE Sync, which could improve performance. They also want to enable their system to handle text data, which would be an important step toward generating an audiovisual large language model.This work is funded, in part, by the German Federal Ministry of Education and Research and the MIT-IBM Watson AI Lab.
- Trending
- Comments
- Latest

Recent News
Stay ahead with the latest insights on Hong Kong’s economy, finance, and investments. From market trends to policy updates, we bring you in-depth analysis and expert opinions.
📩 Subscribe to our newsletter for exclusive updates.
📍 Follow us on social media for real-time news.
📧 Contact us: info@hongkong-invest.com